ZOTACGPUs
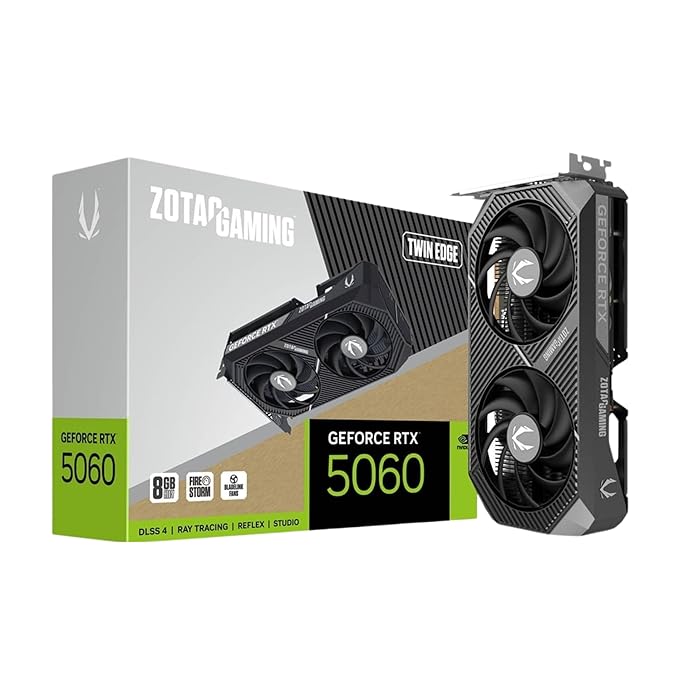
ZOTAC Gaming GeForce RTX 5060 Twin Edge 8GB Graphics Card - Black | 8 GB | DLSS4 | GDDR7 | PCIE 5.0 | SFF Ready | 3840 CUDA Cores | ZT-B50600E-10M
- NVIDIA GeForce RTX 5060
- 2497 MHz
Check today's price on Amazon
Sold by Amazon India
Local-first AI hardware
Accelerators, workstations and memory picked for local inference — with the specifications that actually matter listed in the open, so you can compare a 48 GB accelerator with a 128 GB workstation and know what you are buying.
Featured build-outs
A rotating selection from the catalogue. Availability and pricing come straight from live inventory — nothing here is a placeholder number.
ZOTACGPUs
Sold by Amazon India
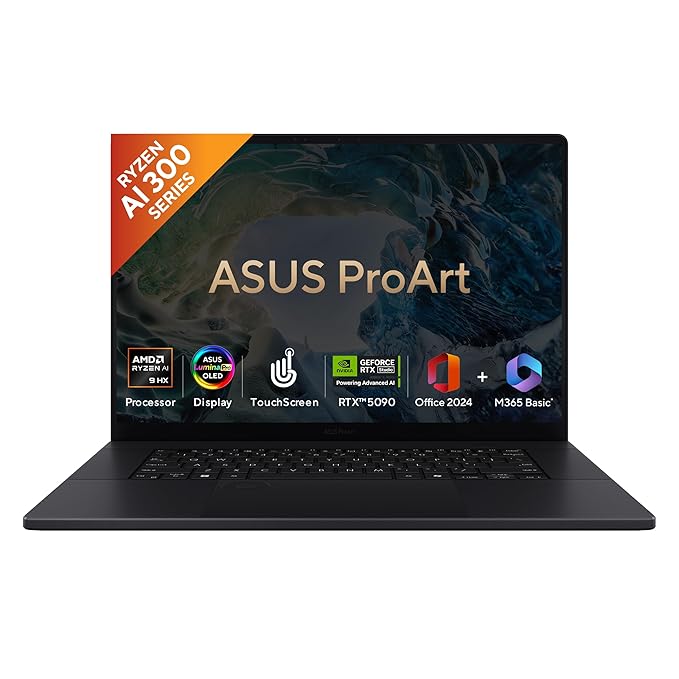
ASUSGPUs
Sold by Amazon India
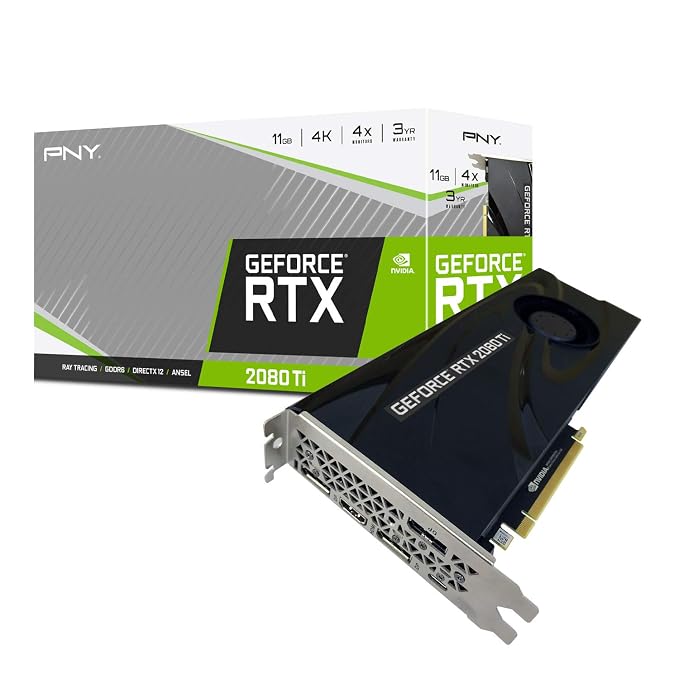
PNYGPUs
Sold by Amazon India
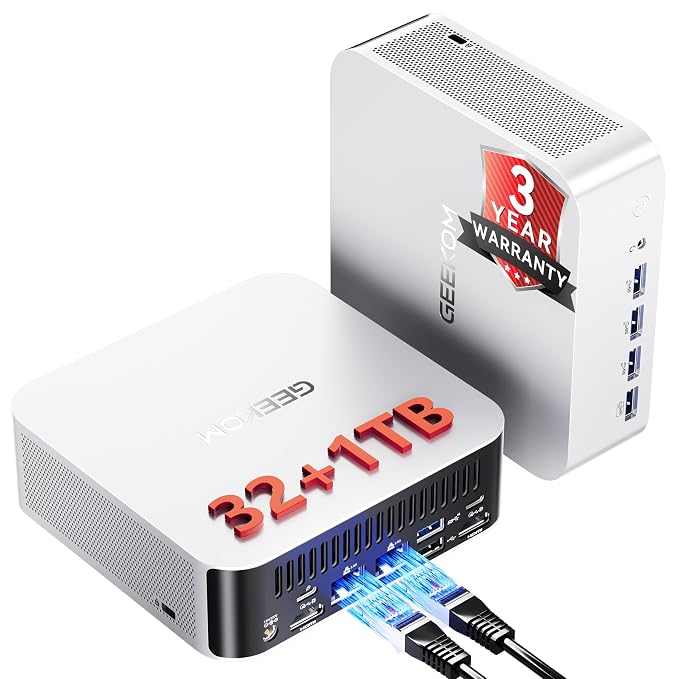
GEEKOMWorkstations
Sold by Amazon India
Categories
Every category links to a filtered view — filters and page numbers live in the URL, so a result set is easy to share with your team.
Dedicated inference and training accelerators.
High-VRAM graphics cards for local model inference.
GPU-equipped machines for local AI.
Compact boards and devices for on-device inference.
Small-form-factor machines with unified memory.
High-capacity memory and fast NVMe storage.
Memory first
Model weights have to fit in memory before anything else matters. Buy for the model and the context window you actually need, then check bandwidth, power and cooling around it.
These bands are rounded estimates. Quantisation, context length and batch size all move them — always leave headroom.
Usable memory → model size
4-bit quantised
Bandwidth drives tokens per second; capacity decides whether a model fits at all.
Learn
Every listing here advertises a number. The guide explains which numbers decide whether a model fits, and the posts run that arithmetic on specific models — including the ones where the API is the cheaper answer.
Buying guide
Updated 01 Nov 2026
4 chapters · memory, class, power, shortlist
Read the guideLatest writing
All postsPrices, tokens per second, break-even
BrowseWhy local AI
Hosted inference is convenient until your workload becomes steady. At that point the trade-offs flip toward hardware — in privacy, in cost and in control.
Inference runs locally, so sensitive data never leaves your network. No third-party retention to reason about.
You buy the hardware once. After that, long-running jobs and experimentation have no per-token bill attached.
Your throughput is bounded by your own silicon, not by a provider’s quota — useful for batch jobs and agent loops.
Available now
Stock levels shown are the live quantities the API reports for these listings.
GenericMemory & Storage
Sold by Amazon India
AMDAI Accelerators
Sold by Amazon India
ASUSGPUs
Sold by Amazon India
ASUSGPUs
Sold by Amazon India
Start here
The buying guide walks through memory, accelerator class and system balance in the order those decisions actually matter.
Lowest entry point
Every listing states who sells it — swaymAI or a partner merchant.
Stay in the loop
We will only send you something when there is a genuinely new listing or a guide worth reading.
Email delivery may be disabled on this deployment — we will always tell you what the API actually did.